Why are the major players in artificial intelligence starting to embed invisible watermarks in their content? The first answer looks obvious: to comply with the AI Act. It is correct, but it is incomplete.
The obvious answer: article 50 of the AI Act
Article 50 of the European regulation requires providers of systems generating text, images, audio or video to make their output identifiable and marked in a machine-readable format. The obligation is not about a notice visible on screen; it is about a signal that anyone downstream in the chain can process automatically.
What the major providers are doing fits that logic plainly. Anthropic now embeds a statistical signal in certain texts produced by Claude. OpenAI uses C2PA metadata and SynthID watermarks, among other things, for certain visual and audio content, with the aim of extending those provenance signals to further formats.
The web has become both the source and the sink
Reducing the watermark to a regulatory formality would arguably miss a deeper issue.
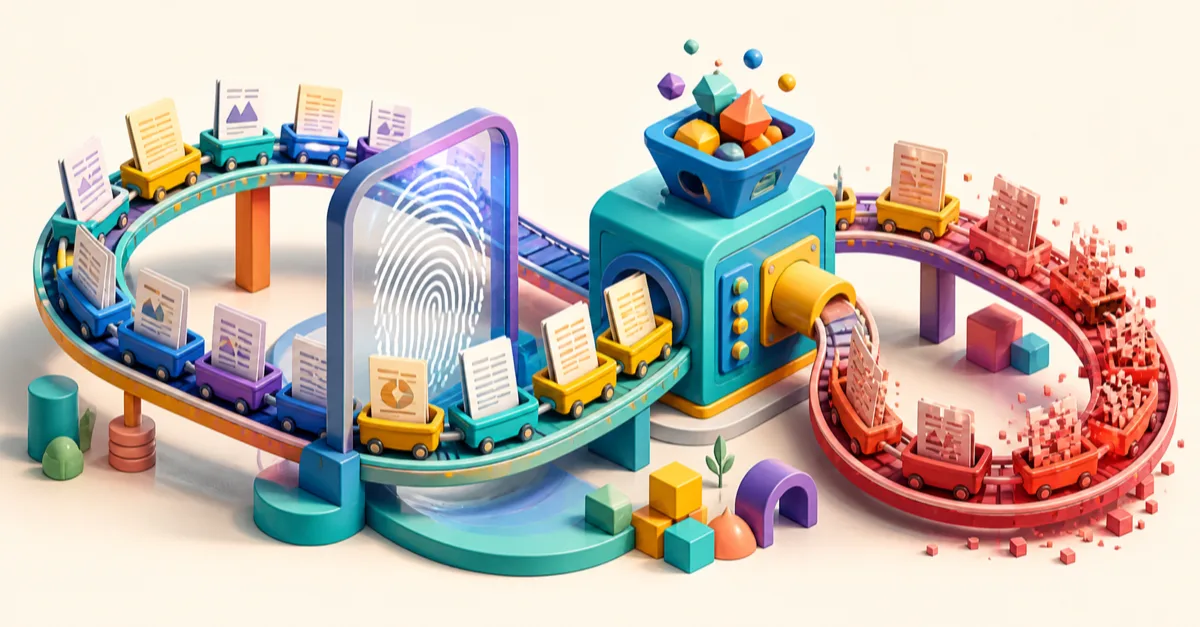
The web is becoming at once the library in which AI systems learn and the space into which they pour their own output. If the coming generations of models are trained indiscriminately on growing volumes of synthetic content, they risk reproducing their own approximations, amplifying certain errors, and gradually losing the diversity present in human data.
That phenomenon is called model collapse. The work published in Nature on recursive training shows that the degradation does not first appear as spectacular errors, but as the silent disappearance of rare cases: the distribution tightens around its own mean.
The watermark as a data governance tool
Seen that way, the watermark changes in nature. In theory it would let platforms, search engines and dataset builders tell human content from synthetic content, then flag it, filter it or weight it differently.
In other words, a marking deployed today to satisfy a regulator could serve tomorrow to protect the resource the whole industry depends on: training data whose origin remains possible to qualify.
What the watermark does not prove
That benefit stays indirect, though, and the limits deserve to be stated without indulgence.
- No watermark guarantees that content is true; a marked text can be false, an unmarked text can be accurate.
- No watermark guarantees that the content has not been altered since it was generated.
- The technique stays particularly fragile for text: a rewording or a paraphrase can be enough to disturb a statistical signal.
- Metadata can disappear during a conversion, a compression, or a share on a platform that re-encodes files.
The direct consequence: the absence of a mark does not prove human origin. A ranking system treating the watermark as proof, rather than as an indication, would get it wrong in both directions.
Three levels of one question
The answer to the opening question is probably this. Watermarks are deployed first to meet the transparency obligations of the AI Act. They can then help search engines better qualify the provenance of content. And in the longer run, they could help protect future models against being fed synthetic data without control.
So it may not be a choice between regulation, quality of the web and survival of the models. It is the same question seen at three different levels: legal, informational and technological.
What this means for a company
For an organisation that produces or uses content, three habits become useful straight away.
- Record the origin of your own corpora. Knowing what, in a document base, was written by a human, reviewed by a human, or generated by a model is governance information, not an editorial detail.
- Do not confuse marking with validation. Provenance is traced, truth is verified. Those are two distinct mechanisms with two distinct owners.
- Preserve your human data. Archives predating the generative wave, internal minutes, working correspondence: these form an asset whose relative value rises as the public web turns synthetic.
That is exactly the logic we apply in BrainDup: every answer rests on identified sources, and the origin of ingested documents stays traced end to end. To discuss it, book a meeting or write to us.
The question that stays open
One essential question remains: should we treat the watermark as a simple indication of provenance, or should it also become a criterion for ranking, selection and training?
The answer is not only technical. It will decide what, tomorrow, has the right to learn from what.
Sources and further reading
- The European regulation on artificial intelligence: official text, article 50 in particular
- Overview and topic-by-topic access to the AI Act
- Anthropic: Claude text watermark
- Liora: principles and uses of AI watermarking, in French
- Sean Goedecke: limits and fragility of watermarks applied to text
- OpenAI: Content Credentials, C2PA and SynthID
- Wikipedia: model collapse in artificial intelligence
- Nature: effects of recursive training on AI-generated data
- AS3P (11 August 2026): "The AI Act: how BrainDup answers it, article by article"